1 Conjecture
Given an RGB image and a depth map, the VLM constructs scene semantics, candidate object concepts, inferred 3D structure, and camouflage mechanisms. These elements form the global prior G3D.
ArgusCogito is a zero-shot segmentation framework inspired by the perceptual strategy of the Hundred-eyed Giant. It reformulates camouflaged object segmentation as a cohesive reasoning process and has the following properties:
ArgusCogito organizes multimodal reasoning into three cognition-driven stages, preserving semantic information from global scene understanding to pixel-level mask correction.
Given an RGB image and a depth map, the VLM constructs scene semantics, candidate object concepts, inferred 3D structure, and camouflage mechanisms. These elements form the global prior G3D.
The scene is adaptively divided along horizontal or vertical directions. Semantic focusing, hypothesis-driven reasoning, and candidate verification recover objects that coarse global reasoning may miss.
SAM 2.1 produces an initial mask. The VLM diagnoses semantic and structural errors, verifies dense positive/negative points, and updates the mask for three refinement rounds.
Under the task-generic prompt setting, ArgusCogito consistently improves over prompt-driven baselines and rivals several supervised RGB-D methods. Lower M is better; higher Fβ, Eϕ, and Sα are better.
| Method | COD10K | CHAMELEON | CAMO | |||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| M ↓ | Fβ ↑ | Eϕ ↑ | Sα ↑ | M ↓ | Fβ ↑ | Eϕ ↑ | Sα ↑ | M ↓ | Fβ ↑ | Eϕ ↑ | Sα ↑ | |
| Qwen2.5 + SAM2 | .126 | .656 | .792 | .734 | .086 | .625 | .786 | .728 | .127 | .591 | .728 | .681 |
| GroundingSAM | .085 | .670 | .813 | .764 | .122 | .662 | .776 | .744 | .157 | .656 | .753 | .707 |
| GenSAM | .058 | .695 | .843 | .783 | .073 | .696 | .806 | .774 | .106 | .669 | .798 | .729 |
| ProMaC | .042 | .716 | .876 | .805 | .044 | .790 | .899 | .833 | .090 | .725 | .846 | .767 |
| INT | .037 | .722 | .883 | .808 | .039 | .801 | .906 | .842 | .086 | .734 | .853 | .772 |
| ArgusCogito | .026 | .824 | .928 | .843 | .035 | .824 | .918 | .859 | .079 | .774 | .866 | .800 |
Table 1. Representative task-generic prompt baselines from the paper. All results are averaged over three runs.
The comparison covers indefinable boundaries, small objects, large objects, occlusion, multiple objects, and complex shapes. ArgusCogito improves both instance completeness and boundary fidelity.
The same task-generic reasoning pipeline transfers from natural camouflage to plant camouflage and medical imagery without task-specific fine-tuning.
| Dataset | Domain | Test samples | M ↓ | Fβ ↑ | Eϕ ↑ | Sα ↑ |
|---|---|---|---|---|---|---|
| CVC-ColonDB | Polyp | 380 | .106 | .518 | .712 | .685 |
| Kvasir | Polyp | 100 | .086 | .725 | .828 | .794 |
| ISIC | Skin lesion | 1,000 | .121 | .782 | .813 | .777 |
| PlantCAMO | Plant camouflage | 250 | .112 | .597a | .779 | .694 |
a PlantCAMO reports weighted F-measure Fwβ. Dataset split sizes follow the supplementary material.
The supplementary experiments separate the contribution of the cognitive chain from the underlying backbone and raw depth cues.
| Setting | M ↓ | Fβ ↑ | Eϕ ↑ | Sα ↑ |
|---|---|---|---|---|
| Qwen2.5 + SAM2 | .126 | .656 | .792 | .734 |
| ArgusCogito | .026 | .824 | .928 | .843 |
The gains are not explained by the foundation models alone. The structured cognitive chain is required to unlock fine-grained spatial grounding.
| RGB | Depth | Reasoning | M ↓ | Fβ ↑ | Sα ↑ |
|---|---|---|---|---|---|
| ✓ | – | – | .126 | .656 | .734 |
| ✓ | ✓ | – | .056 | .628 | .742 |
| ✓ | ✓ | ✓ | .026 | .824 | .843 |
Depth alone is unstable. It becomes useful when the reasoning chain interprets it as a context-dependent geometric scaffold.
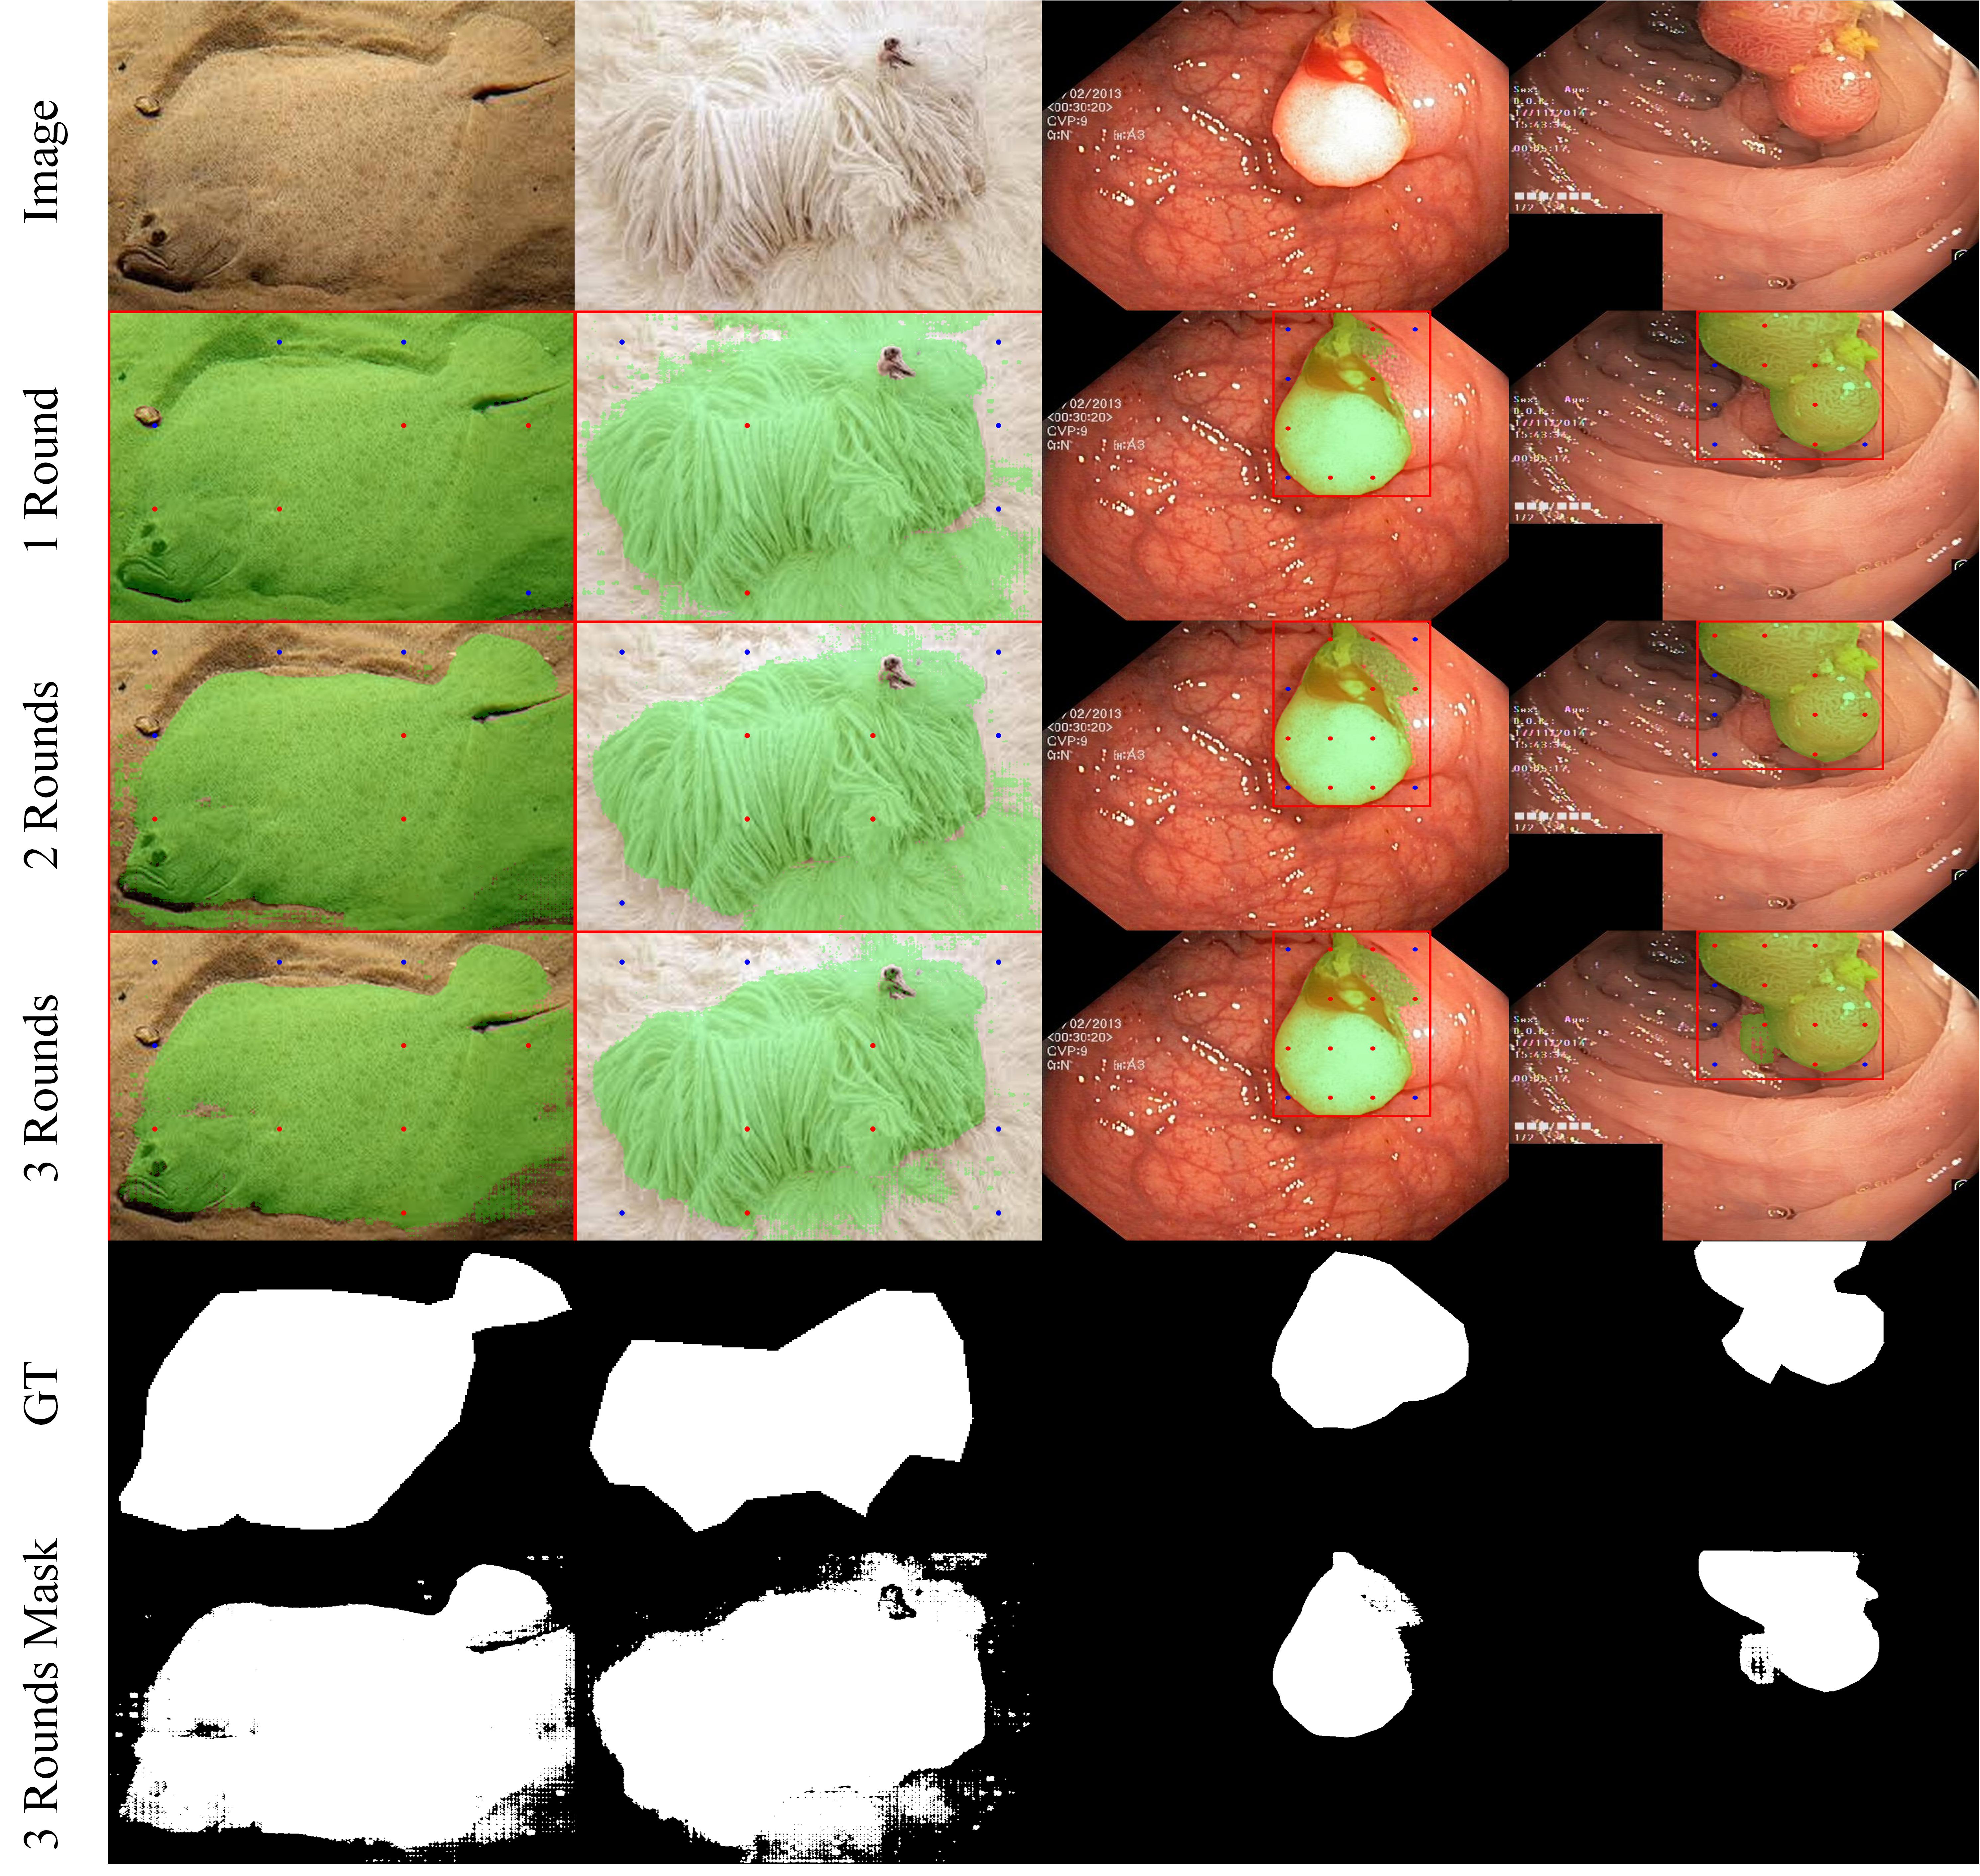
| Strategy | M ↓ | Fβ ↑ | Eϕ ↑ | Sα ↑ |
|---|---|---|---|---|
| single-left | .081 | .758 | .862 | .797 |
| single-up | .079 | .761 | .863 | .797 |
| double | .083 | .752 | .859 | .798 |
| five | .085 | .746 | .862 | .795 |
| adaptive | .079 | .774 | .866 | .800 |
| Iterations | M ↓ | Fβ ↑ | Eϕ ↑ | Sα ↑ |
|---|---|---|---|---|
| 1 | .079 | .759 | .860 | .795 |
| 2 | .080 | .765 | .862 | .794 |
| 3 | .079 | .774 | .866 | .800 |
Task-aligned prompts that encode structural or biological priors are the most stable. Prompts emphasizing full-body coverage, reduced fragmentation, or domain-specific cues improve reasoning consistency; vague conversational requests often fail to trigger effective spatial abstraction. The analysis suggests that semantic precision matters more than prompt length.
Seven benchmarks cover natural camouflage, plant camouflage, polyp segmentation, and skin lesion segmentation.
10,000 images across 10 superclasses and 78 subclasses; 2,026 test images are evaluated.
76 complex natural images for testing generalization in unseen high-ambiguity scenes.
2,500 images; the 250-image test split includes natural camouflage and body painting.
Colonoscopy frames with diverse polyps, evaluated under the PraNet partition protocol.
High-quality polyp masks spanning varied shapes, textures, sizes, and imaging artifacts.
A standard dermoscopic skin-lesion benchmark with cross-institutional variation.
High-resolution, instance-annotated plant camouflage images with strong inter-class similarity.
The supplementary material provides full comparisons with GenSAM and ProMaC across five representative benchmarks.
Global full-resolution reasoning and iterative refinement improve boundary precision and shape completeness in visually homogeneous scenes.
Dynamic spatial focus suppresses false positives caused by subtle texture and luminance differences while preserving complete object structure.
Task-generic prompting and the structured reasoning chain remain robust across rare categories and complex natural backgrounds.
Geometry, semantics, and spatial layout enable domain transfer to fine-grained plant camouflage without specialized adaptation.
Prompt-informed spatial reasoning preserves coherence in polyps and skin lesions despite low contrast, flattened geometry, and unfamiliar clinical imagery.
Camouflaged Object Segmentation (COS) is challenging because targets and backgrounds are highly similar in color, texture, and structure. Existing methods often rely on shallow feature representations, limited reasoning, or weak cross-modal integration, leading to missed instances and inaccurate boundaries. Inspired by the perceptual strategy of the Hundred-eyed Giant, we introduce ArgusCogito, a zero-shot chain-of-thought framework for cross-modal synergy and omnidirectional reasoning within Vision-Language Models.
ArgusCogito contains three cognition-inspired stages. Conjecture constructs a global cognitive prior through RGB-depth-semantic reasoning. Focus performs adaptive omnidirectional scanning and candidate verification. Sculpting generates high-fidelity masks through iterative semantic feedback and dense positive/negative point prompts. Evaluations across camouflaged object segmentation, medical image segmentation, and plant camouflage detection demonstrate strong accuracy, robustness, and cross-domain generalization.
Qwen2.5-VL-7B-Instruct provides multimodal scene understanding, fine-grained visual grounding, and point-wise semantic verification.
SAM 2.1 Hiera Large generates initial masks. A SAM4MLLM-derived binary classifier verifies point prompts during Sculpting.
Depth Anything V2 pre-generates monocular depth maps, adding dense geometric context for low-contrast or cluttered scenes.
The pipeline supports batched stage-wise execution and sequential single-image execution. Images are resized to a maximum long edge of 1,500 pixels.
Experiments use NVIDIA A100 40 GB GPUs, organized as four two-GPU pairs for large-scale inference and ablation studies.
Task-generic prompts identify camouflaged animals, camouflaged plants, polyps, or skin lesions without spatial priors or task-specific training.
Infrared and thermal inputs could improve robustness in low-light, occluded, or safety-critical environments.
Dynamic zoom-in and hierarchical decomposition may better handle ultra-small targets and dense-object scenes.
Lightweight fine-tuning or a dynamic camouflage-pattern lexicon could inject specialized domain knowledge.
Industrial defect detection and temporally consistent video segmentation are promising extensions.
@article{tan2025arguscogito,
  title   = {ArgusCogito: Chain-of-Thought for Cross-Modal Synergy and
             Omnidirectional Reasoning in Camouflaged Object Segmentation},
  author  = {Tan, Jianwen and Zhang, Huiyao and Xiong, Rui and Zhou, Han
             and Wang, Hongfei and Li, Ye},
  journal = {arXiv preprint arXiv:2508.18050},
  year    = {2025}
}